A New MacBook Air, the Memory Crunch, and the Future of AI
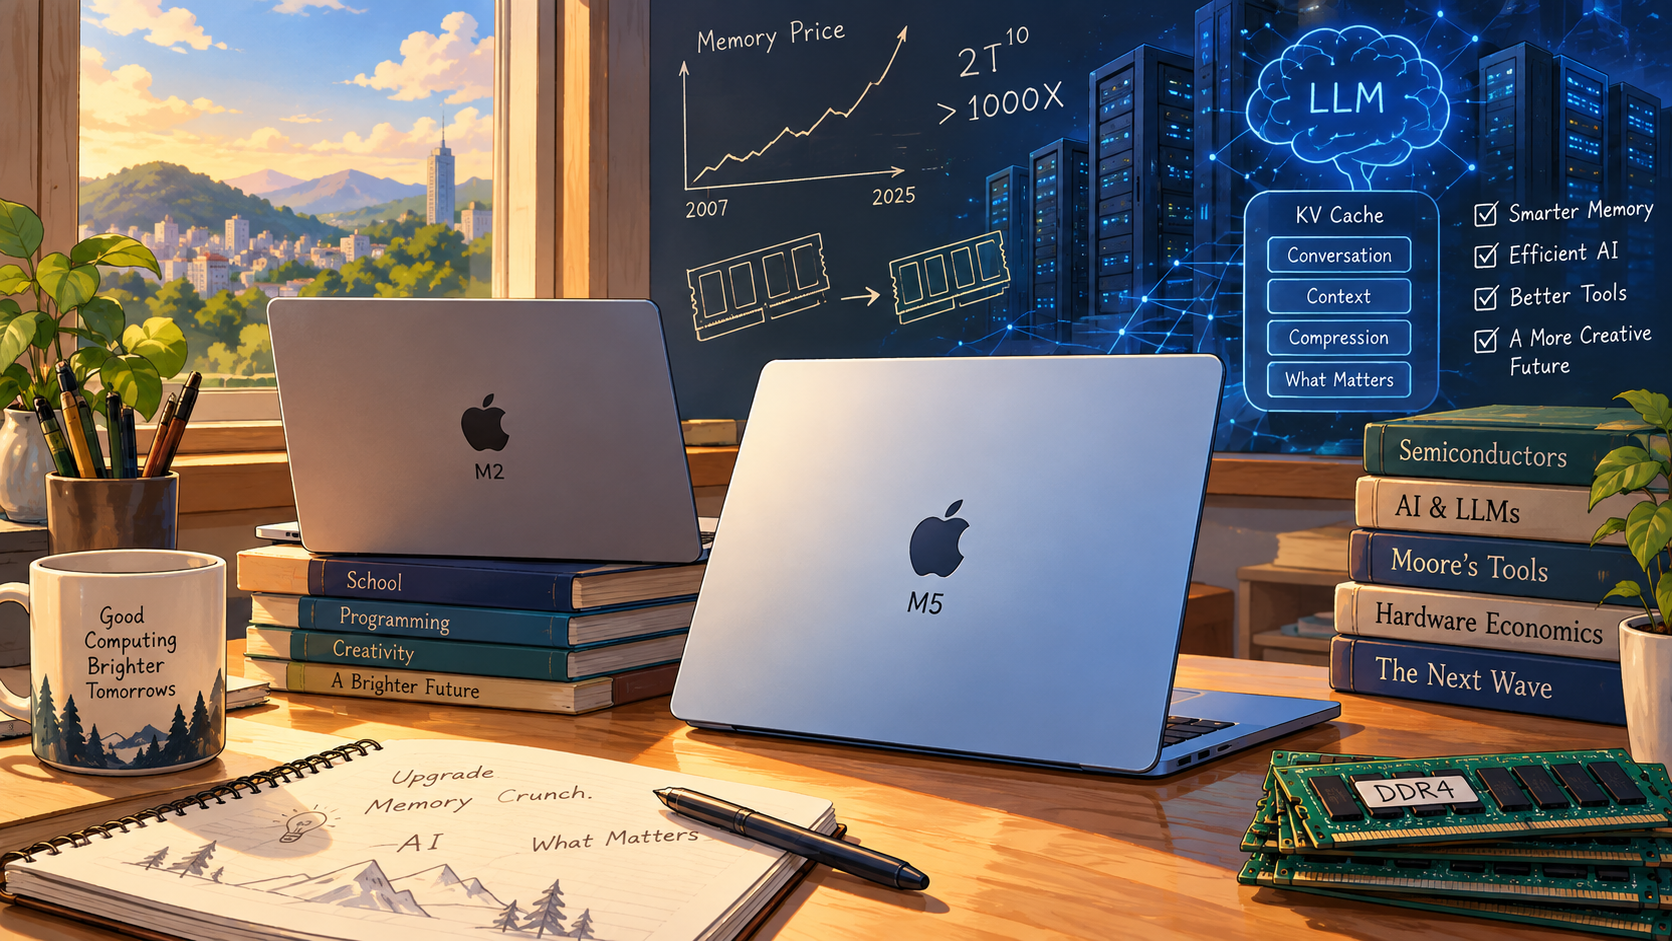
I eventually upgraded my MacBook Air to an M5. Not because I needed the additional performance, but because my son was looking to move on from his ThinkPad. Seeing that his sister had already become a Mac user, he decided he wanted to follow in her footsteps.
After comparing the specifications of the MacBook Neo and my existing M2 MacBook Air, I concluded that the M2 was still the superior machine overall. So, rather than buying him a new entry-level Mac, I decided to pass my perfectly capable M2 on to him and treat myself to an M5.
There was another reason for the timing: I managed to secure the M5 at a good price amid concerns about rising memory costs.
The explosive demand for AI hardware has created a severe crunch in the memory market. Traditionally, semiconductor scaling has meant that technology becomes increasingly affordable over time. Yet supply and demand occasionally fall out of balance, sending memory prices soaring. We seem to be revisiting the kind of memory pricing volatility we experienced back in 2007.
While the semiconductor industry no longer follows the classical interpretation of Moore’s Law as closely as it once did—roughly doubling transistor density every 24 months at a comparable cost—the long-term trajectory of exponential improvement remains remarkable.
Consider the nearly two decades since 2007. At a doubling every two years, that’s approximately ten generations of improvement, or 2^10—more than a 1,000-fold increase. Of course, this is a theoretical illustration rather than a literal 1,000-fold improvement in memory capacity or cost. Still, it puts today’s technology into perspective. From that angle, a MacBook Air equipped with 24GB of unified memory remains an impressive machine and, to me, a great deal.
Interestingly, when I recently assembled my own AI machine for OpenClaw and agentic AI experiments, I found myself digging through my old hardware collection. Rather than paying today’s prices for new memory, I reused some DDR4 modules left over from an earlier build. Sometimes, the most sensible upgrade is simply making better use of what we already have.
This brings up a more interesting question: What does limited memory capacity actually mean for AI?
Today’s AI landscape is dominated by large language models LLMs. During inference, these models rely on a mechanism called the key-value cache to retain intermediate representations of previously processed tokens. This allows the model to efficiently attend to earlier parts of a conversation without repeatedly computing everything from scratch.
The challenge is that the KV cache grows as the context becomes longer. With limited memory, a model may struggle to accommodate long conversations, large documents, or multiple concurrent tasks. In more extreme cases, memory constraints can restrict the models we can run, their context windows, or their overall inference performance.
And perhaps that’s where the next wave of innovation will emerge.
Instead of relying entirely on larger memory capacities and ever-expanding context windows, we may see greater emphasis on smarter approaches to memory management: compressing conversations, selectively retaining relevant information, summarizing historical context, and extracting the essential knowledge from past interactions.
After all, remembering everything is not necessarily the same as understanding what matters.
Perhaps the next breakthrough in AI won’t simply be about giving machines more memory, but teaching them what is worth remembering.